How I found a <head> polluted with eight <title> tags and a homepage serving another page: the Vicent Florencia case
Can a site look perfect when browsed while serving broken HTML to anyone who doesn't execute its JavaScript?
By Pietro Fiorillo ·
In this article
The documented problem: a personal portfolio that needed to look professional from the first click
Vicent is a dancer and classical ballet and contemporary dance teacher in Madrid. He needed a site that conveyed aesthetic sensitivity without losing commercial clarity, with an «About» section, services, a gallery and a direct contact channel to book classes.
Why I decided to ask the site exactly what a crawler asks it
I don't have access to this project's repository. Instead of just describing the documented architecture, I used curl to request the homepage exactly as a search engine would: with no JavaScript execution, reading only the HTML the server returns up front.
What I found: a head with eight titles and a body that doesn't match
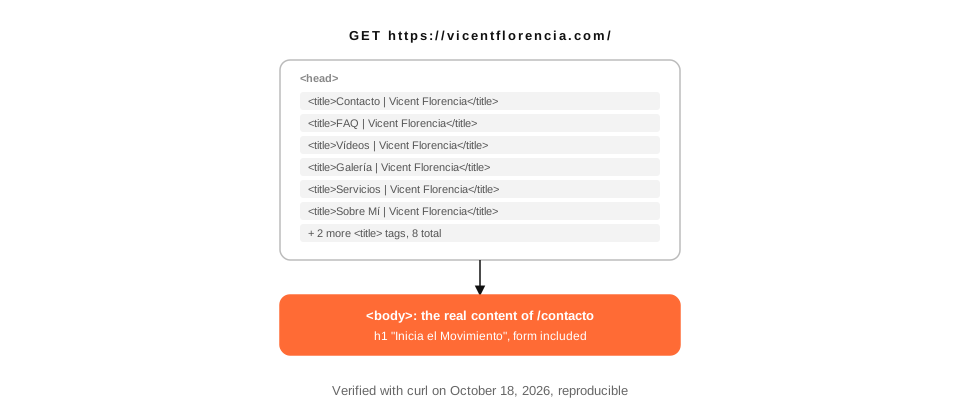
The <head> of https://vicentflorencia.com/ contains eight consecutive <title> tags: Contact, FAQ, Videos, Gallery, Services and Classes, About Me, the homepage's full title, and an eighth generic one. It's not a single tag with a long text: it's eight distinct <title> elements, one after another.
Even more striking: the <body> that follows that head isn't the homepage's. It's, literally, the content of the /contacto page: the «Inicia el Movimiento» heading, the WhatsApp and Instagram contact block, and the full form with its name, email and service-of-interest fields.
I repeated the request at a different time, in case it was a transient state, and got exactly the same result both times. It's not a passing flicker: it's what the server consistently returns.
Why this doesn't show up when browsing the site
It's an SPA: as soon as JavaScript loads in the browser, the router takes over and shows the correct page based on the URL, including the real homepage. That's why a person browsing the site never sees this problem. Whoever does see it is any system that reads the HTML before executing JavaScript, which is exactly the case for many crawlers and for the preview a social network builds when sharing the link.
Measurable results
| Metric | Result | Environment / evidence |
|---|---|---|
| Lighthouse Performance (mobile, lab) | 91 / 100 | Lighthouse 13.5.0, simulated throttling |
| LCP (lab) | 3.3 s | Same Lighthouse run, not field (CrUX) data |
| <title> tags on the homepage | 8 | Confirmed twice with curl at different times |
| URLs in the sitemap | 12 | Public sitemap.xml, confirmed with curl |
A site that looks perfect isn't the same as a site that works well. The first is judged by a person browsing it; the second, by anyone reading the HTML exactly as it arrives.
My part in this project
My part in Vicent Florencia included the personal brand design and the site's development, as part of my work at MANYA Digital.
What I'd do differently: a production bug I had no way of seeing without checking the raw HTML
This is, directly, a real defect on the production site, not an inaccuracy in how I documented it. I don't have repository access right now to fix it, but I'm leaving it documented as precisely as possible: the most likely cause, from what I can observe externally, is a static HTML generation script that doesn't reset the <head> between one route and the next, and that at some point saved the wrong body for the homepage.
What I'd test next
If I had repository access, my first step would be to review the script that generates each route's static HTML, confirm it resets the document before processing the next page, and add a simple automated check (counting the <title> tags on each published route) so a problem like this gets caught in minutes instead of a manual review like this one.
Sources
Frequently asked questions
What does it mean to have eight <title> tags on a single page?
That the document's head accumulated the title of each of the site's eight pages, instead of only the one matching that URL. It's a symptom of an HTML generation process that doesn't reset state between one page and the next.
Does this affect what a person sees browsing the site?
Once the site's JavaScript loads in the browser, the app takes over and shows the correct page based on the route. The problem is specific to the HTML served before JavaScript runs, which is exactly what crawlers see and what determines the title Google can show in results.
Why is the body served on the homepage the contact page's?
I don't have repository access to confirm the exact cause, but the pattern is consistent with a prerender script that visits every route and saves the resulting HTML, and at some point the homepage's file ended up overwritten with the last visited route's content instead of its own.
Is this an isolated case, or did you see it elsewhere?
In this same series I documented a different prerendering problem (missing, not corrupted) on another project, and confirmed it works correctly on a third. Each case has a different cause; what they share is that none of them are noticeable just browsing the site.
How did you verify this with no code access?
I requested the homepage with curl twice, at different times, and got the same result both times: eight <title> tags, a body with the contact form. It's not a tooling error on my end, it's what the server consistently returns.
How would this get fixed?
By reviewing the static HTML generation script to confirm it resets the head (and saves the correct body) before processing each new route. With no repository access, I can't say more than that.